OpenAI's Faster Fourier Transforms: Math and Reality
CATEGORY: Web Dev
A look at the math that OpenAI claims computes faster Fourier transforms raises a practical question: does a better mathematical bound make your software faster? For audio tools, waveform dashboards, and sensor-data applications, the answer matters. For ordinary websites, it probably does not.
OpenAI has published a theoretical result that improves the asymptotic arithmetic-operation bound for the discrete Fourier transform (DFT). The distinction is theoretical operation counts versus actual execution time. Here is how to evaluate the claim before changing production code.
1. Understand the DFT and Why FFTs Matter
Step 1: Recognize a frequency-domain problem
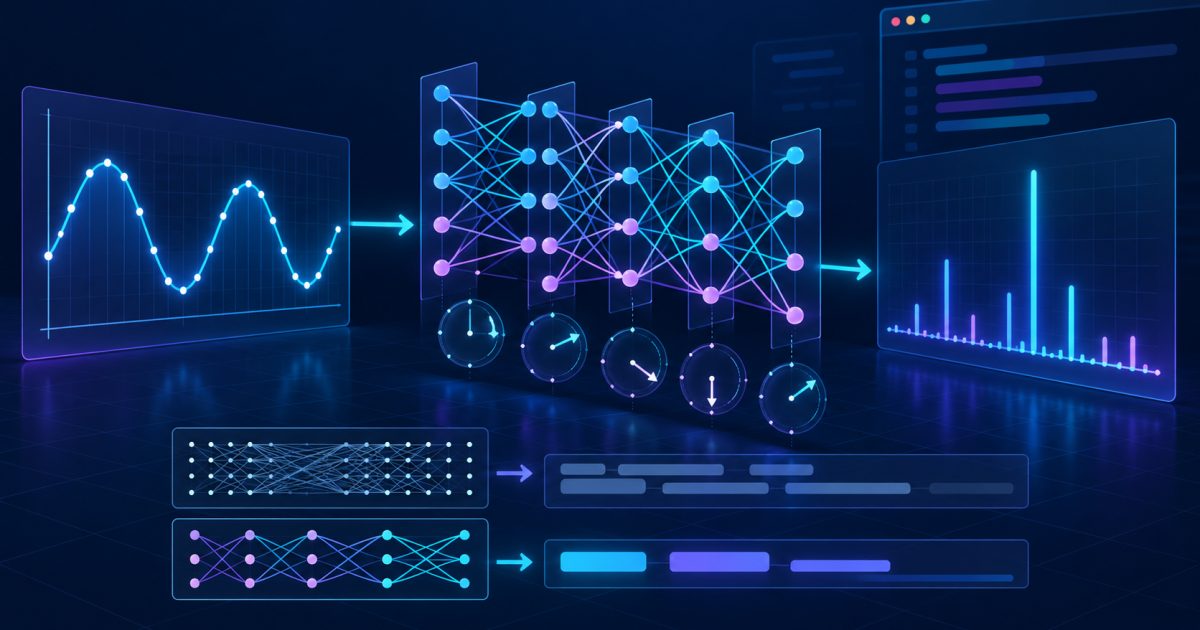
An audio file stores samples that describe how a signal varies over time. A frequency-domain representation helps reveal repeating components: low-frequency rumble, higher-frequency tones, or peaks used by a visualizer. Related tools appear in filtering, convolution, and image processing.
The DFT converts N input samples into N complex-valued frequency coefficients:
X[k] = sum(n=0 to N-1) x[n] * exp(-2*pi*i*k*n/N)Computing each coefficient independently takes roughly O(N²) operations. A fast Fourier transform (FFT) computes the same DFT more efficiently.
Step 2: See where the speed comes from
A radix-2 FFT splits samples into even and odd positions, solves smaller transforms, and combines results using twiddle factors. Its work grows as O(N log N).
That matters for repeated signal processing, not normal page speed. Slow business sites more often need caching, database profiling, or asset optimization.
2. Read OpenAI's Claim Precisely
Step 1: Check the published bound
In its mathematics research release, OpenAI links to a collection of research results. Its formalization summary for result 130 describes a deterministic exact-DFT computation with work bounded by:
O(N * (log N)^(1 - 10^(-13)))The exponent is slightly below one, giving asymptotically lower growth than N log N in that model. It does not promise any particular real-world speedup.
Step 2: Understand the exact-arithmetic model
The result uses exact complex arithmetic with unrestricted coefficients. Certain operations on complex quantities count as individual arithmetic steps. Actual CPUs, GPUs, and JavaScript runtimes use finite representations and must account for precision, memory movement, and implementation overhead.
The summary distinguishes a subsequential circuit result from a separate uniform result covering every input length. It makes no bounded-coefficient, conditioning, or bit-complexity claim.
An arithmetic-circuit theorem is not a stable floating-point implementation. In particular, a processor cannot treat arbitrarily precise complex-number multiplication as a universally constant-cost instruction. Precision requirements and coefficient sizes can affect whether an abstract operation is practical.
That is why the formalized statement should be read within its declared model, rather than as a shipping software feature.
Step 3: Treat criticism as part of the evidence
Researcher Ben Recht discusses the claim in Faster Fourier Transforms. His central concerns involve large hidden constants and arithmetic assumptions disconnected from practical hardware.
These objections challenge engineering usefulness, not necessarily mathematical validity.
For site owners, the conclusion is simple: there is no demonstrated reason to replace a working FFT library merely because of this theoretical result.
3. Understand Why Better Big-O Can Still Be Slower
Step 1: Examine hidden constants
Big-O describes growth for large inputs, not actual milliseconds.
For example, a hypothetical 10^15 * N routine has better asymptotic growth than N log N, yet could be dramatically slower at every realistic size.
This is an illustration, not a benchmark of OpenAI's method.
Step 2: Include precision and memory costs
A transform loads data, allocates buffers, and writes results. Large intermediate values can also create precision or stability problems.
Before comparing two FFT implementations, require equivalent answers to these questions:
- Do they compute the same transform and normalization?
- What input sizes and numerical precision are supported?
- Are setup, memory allocation, and data transfers included?
- Does performance improve on the hardware you actually use?
A lower operation count is worthwhile research. A faster production system needs reproducible measurements and acceptable error bounds.
Record transform length, input distribution, library configuration, warm-up procedure, and memory consumption with each benchmark.
Without that context, numbers from different machines or libraries rarely support a fair comparison.
4. Benchmark a Correct FFT in JavaScript
Step 1: Start with a known baseline
This small, self-contained Node.js script implements a radix-2 FFT. It checks a sample signal against the direct DFT, then times several sizes.
It is an educational baseline, not a tuned library.
Save it as fft-benchmark.mjs:
import { performance } from 'node:perf_hooks';

function fft(re, im) {
  const n = re.length;

  if (!n || n !== im.length || (n & (n - 1))) {
    throw new Error('Equal power-of-two array lengths required');
  }

  let j = 0;

  for (let i = 1; i < n; i++) {
    let bit = n >> 1;

    while (j & bit) {
      j ^= bit;
      bit >>= 1;
    }

    j ^= bit;

    if (i < j) {
      [re[i], re[j]] = [re[j], re[i]];
      [im[i], im[j]] = [im[j], im[i]];
    }
  }

  for (let size = 2; size <= n; size *= 2) {
    for (let start = 0; start < n; start += size) {
      for (let k = 0; k < size / 2; k++) {
        const a = start + k;
        const b = a + size / 2;

        const angle = -2 * Math.PI * k / size;
        const wr = Math.cos(angle);
        const wi = Math.sin(angle);

        const tr = wr * re[b] - wi * im[b];
        const ti = wr * im[b] + wi * re[b];

        const ar = re[a];
        const ai = im[a];

        re[a] = ar + tr;
        im[a] = ai + ti;

        re[b] = ar - tr;
        im[b] = ai - ti;
      }
    }
  }
}

const signal = n => Float64Array.from(
  { length: n },
  (_, i) =>
    Math.sin(2 * Math.PI * 5 * i / n) +
    0.25 * Math.cos(2 * Math.PI * 11 * i / n)
);

const input = signal(64);
const re = Float64Array.from(input);
const im = new Float64Array(64);

fft(re, im);

let maxError = 0;

for (let k = 0; k < input.length; k++) {
  let dr = 0;
  let di = 0;

  for (let t = 0; t < input.length; t++) {
    const a = -2 * Math.PI * k * t / input.length;

    dr += input[t] * Math.cos(a);
    di += input[t] * Math.sin(a);
  }

  maxError = Math.max(
    maxError,
    Math.hypot(re[k] - dr, im[k] - di)
  );
}

console.log('Maximum error:', maxError);

if (maxError > 1e-8) {
  throw new Error('FFT correctness check failed');
}

for (const n of [256, 1024, 4096, 16384]) {
  const source = signal(n);

  for (let i = 0; i < 3; i++) {
    fft(
      Float64Array.from(source),
      new Float64Array(n)
    );
  }

  const started = performance.now();

  for (let i = 0; i < 15; i++) {
    fft(
      Float64Array.from(source),
      new Float64Array(n)
    );
  }

  console.log(
    n,
    ((performance.now() - started) / 15).toFixed(3),
    'ms/run'
  );
}
Run it from the same directory:
node fft-benchmark.mjsStep 2: Interpret the output correctly
The correctness check should pass. Timing varies by CPU, load, and runtime. Repeat trials.
This test includes buffer creation but excludes decoding, networking, and rendering.
Importantly, it compares against a direct DFT for correctness, not against OpenAI's research algorithm. It cannot establish whether that new method is faster.
5. Apply Practical Fixes to a Web Application
Step 1: Profile the full pipeline
For uploaded audio, profile decoding, transform, storage, and rendering separately. Faster math cannot fix slow decoding.
Step 2: Keep expensive work off the request path
In a browser, use a Web Worker when repeated transforms make the interface unresponsive.
Workers protect UI responsiveness; they do not magically reduce CPU cost.
On a PHP or Laravel server, move heavy processing into appropriate background jobs and return a job status to the visitor.
If shared hosting complicates long-running workers, see Running Laravel Queues on Shared Hosting Without Supervisor.
Check the host's resource limits before scheduling expensive processing.
Step 3: Prefer measured, maintained implementations
For production workloads, compare established FFT libraries or WebAssembly modules using the same input, output convention, and precision.
Avoid rewriting a battle-tested implementation unless profiling shows a meaningful benefit.
Cache repeatable results, reuse buffers, avoid unnecessary array transfers, and verify results after deployment.
Common problems
FFT outputs look wrong
Check the sample rate, transform direction, normalization, and whether you are plotting magnitude rather than raw complex components.
Zero-padding changes frequency-bin spacing; it does not create new information in the original signal.
A browser tab freezes during processing
Profile both computation and visualization.
Move expensive work to a Worker, limit unnecessary redraws, and benchmark data copying as well as FFT execution.
Benchmark results vary wildly
Warm up the implementation, repeat trials, and avoid running heavy background tasks.
Compare results on the same machine with comparable inputs.
The example rejects my input
The example accepts only power-of-two input lengths.
For arbitrary lengths, use a library with the required length support or deliberately pad the data while understanding its effect.
FAQ
Did OpenAI prove web applications will process audio faster?
No. Its described bound applies to exact arithmetic under specified assumptions; practical floating-point speedups have not been established by that claim.
Is the ordinary FFT inaccurate?
An FFT computes the DFT algorithmically.
Floating-point implementations can introduce rounding error, so accuracy requirements must still be tested for your particular workload.
Should I adopt the OpenAI algorithm now?
Not solely on the research claim.
Wait for a usable implementation, independent benchmarks, documented numerical behavior, and a demonstrated improvement on realistic inputs.
Will this improve SEO or website loading speed?
Not for a typical content site.
Improve Core Web Vitals, caching, asset sizes, server responses, and database performance first.
Fourier-transform optimization helps only where transforms are actually part of the workload.
Summary
The reported bound beats N log N asymptotically, but exact arithmetic and unrestricted coefficients do not imply a fast, stable implementation.
Before changing production code, use this checklist:
- [ ] Confirm that your application really performs FFT calculations.
- [ ] Distinguish theoretical operation counts from measured runtime.
- [ ] Keep the original research assumptions visible in your explanation.
- [ ] Validate numerical results against a trusted reference.
- [ ] Benchmark realistic input sizes and include allocation costs.
- [ ] Profile decoding, data transfers, and rendering too.
- [ ] Move heavy work off user-facing request and UI paths where appropriate.
- [ ] Adopt a new algorithm only after reproducible, relevant speedups.
Bottom line: better mathematics can inspire better software, but deployment decisions should follow tested correctness and real performance—not headlines.